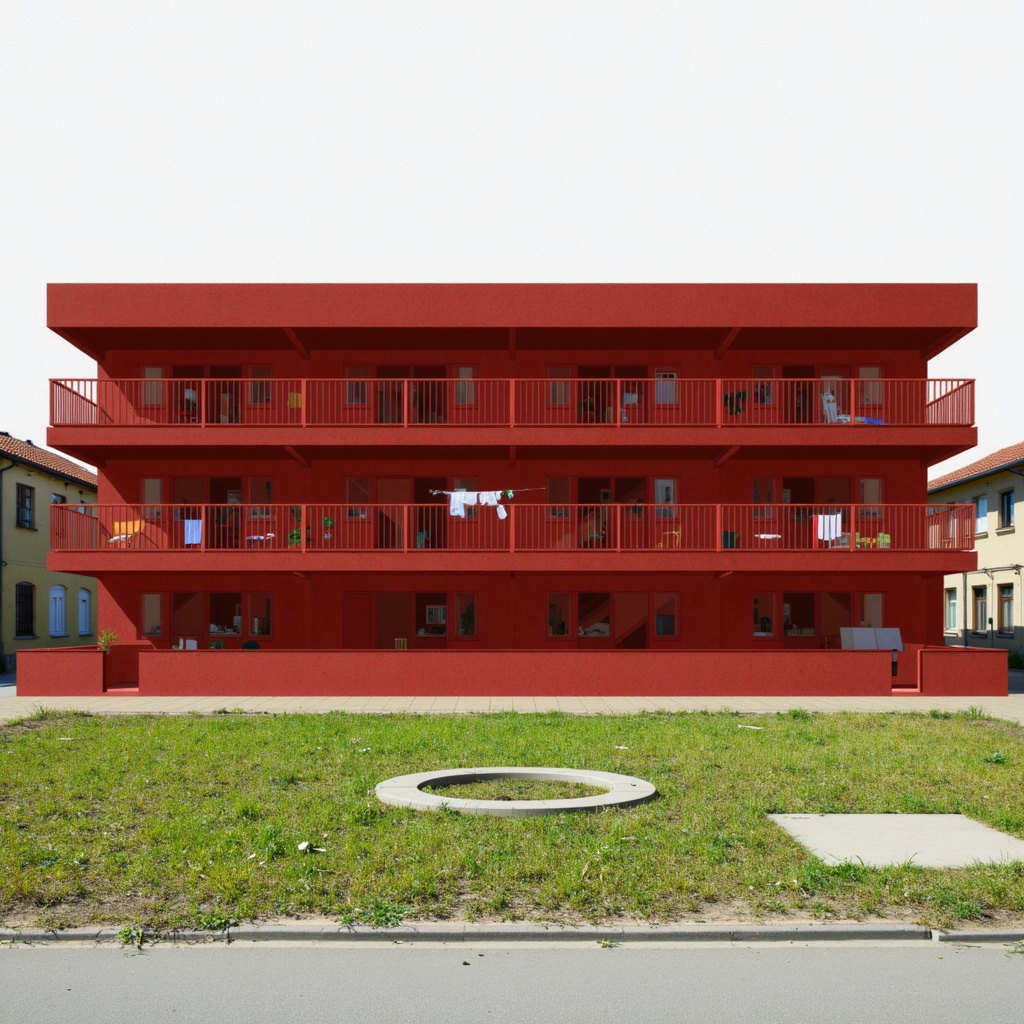
The question
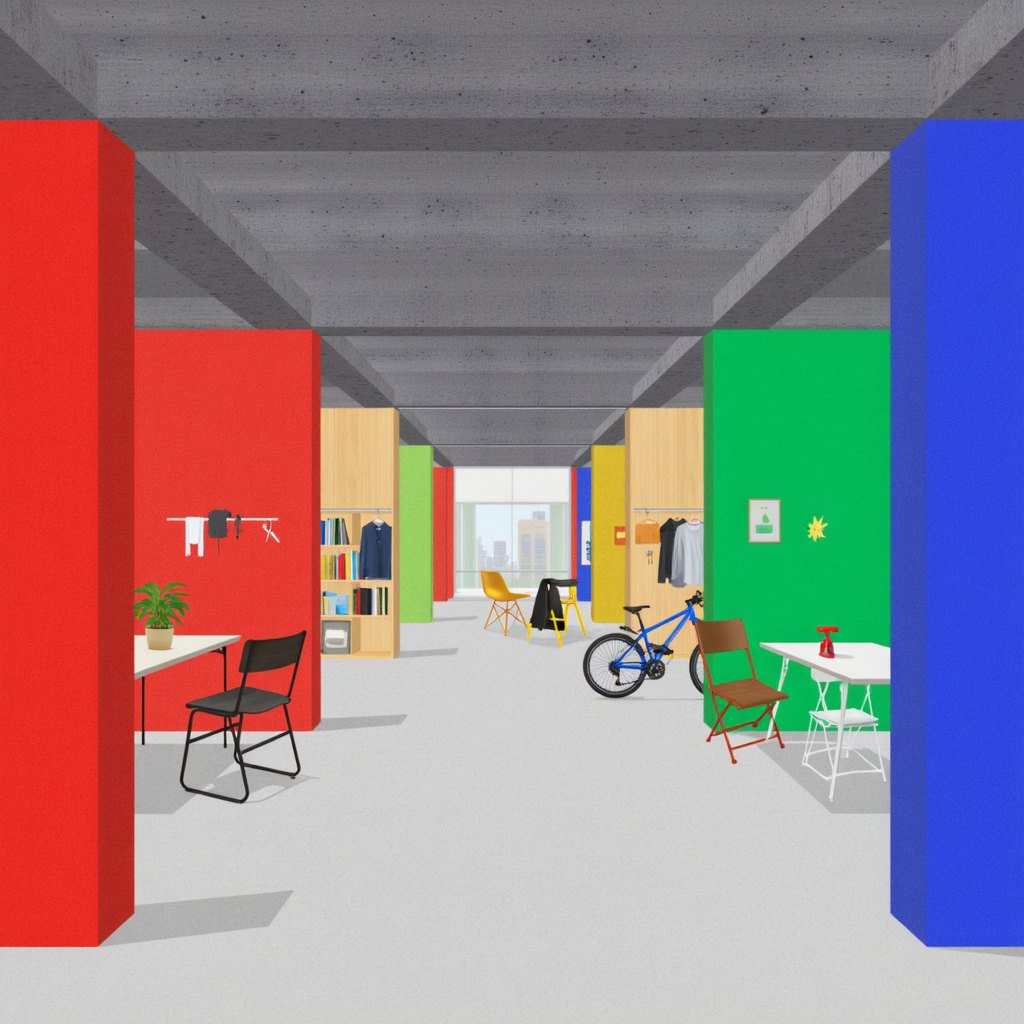
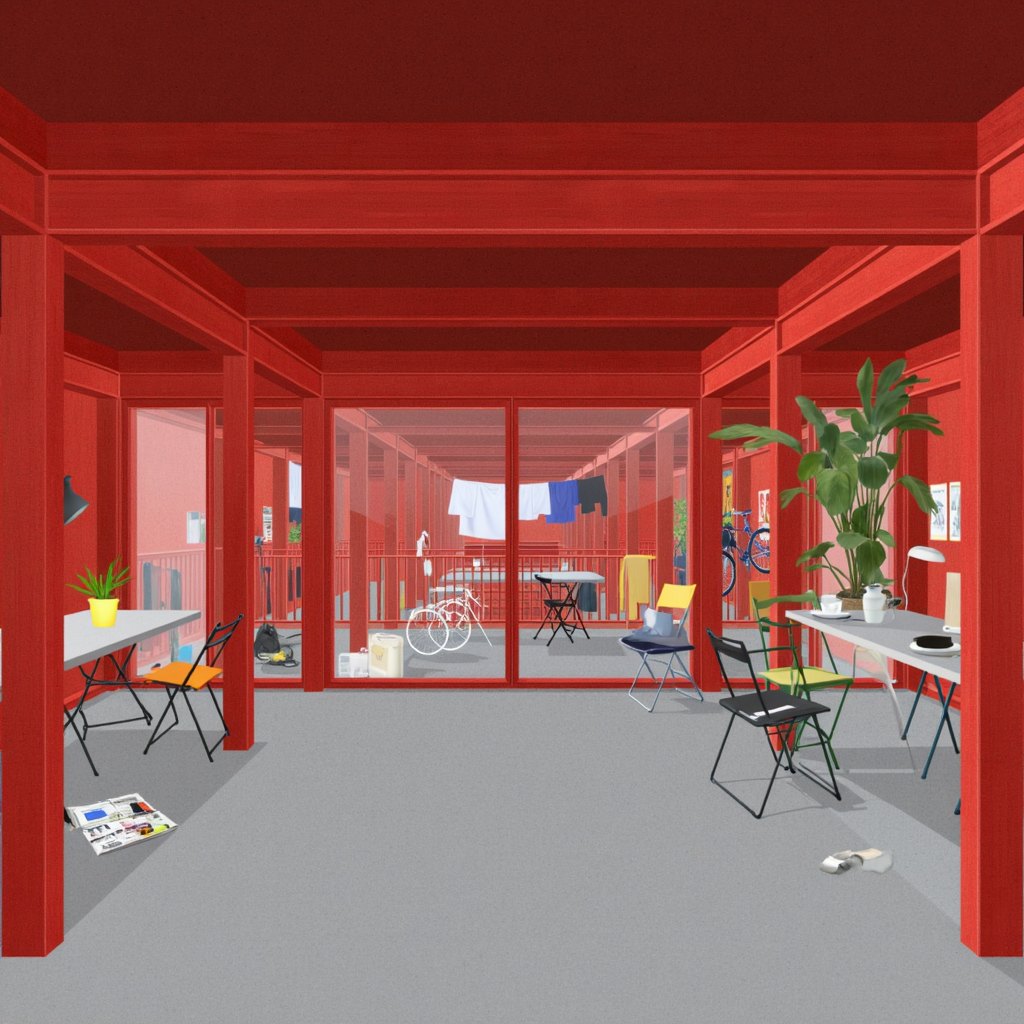
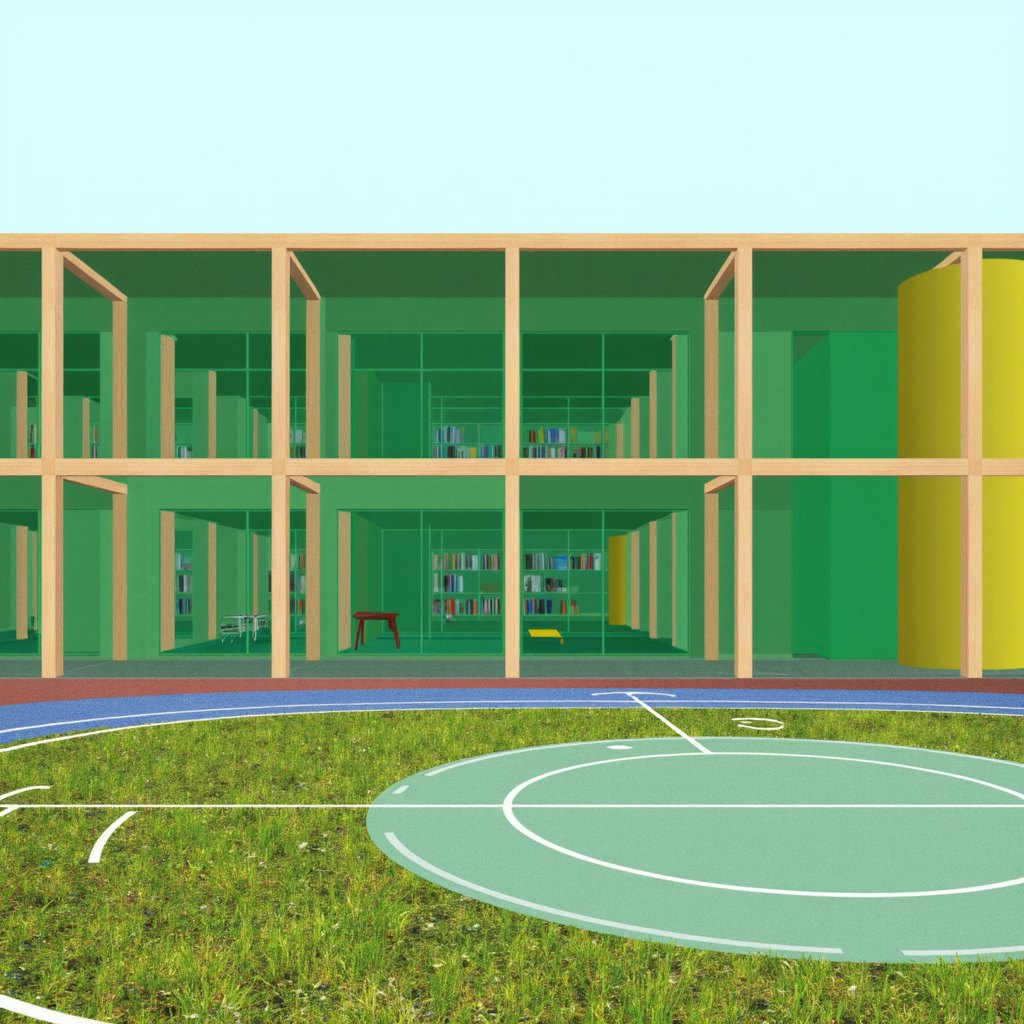
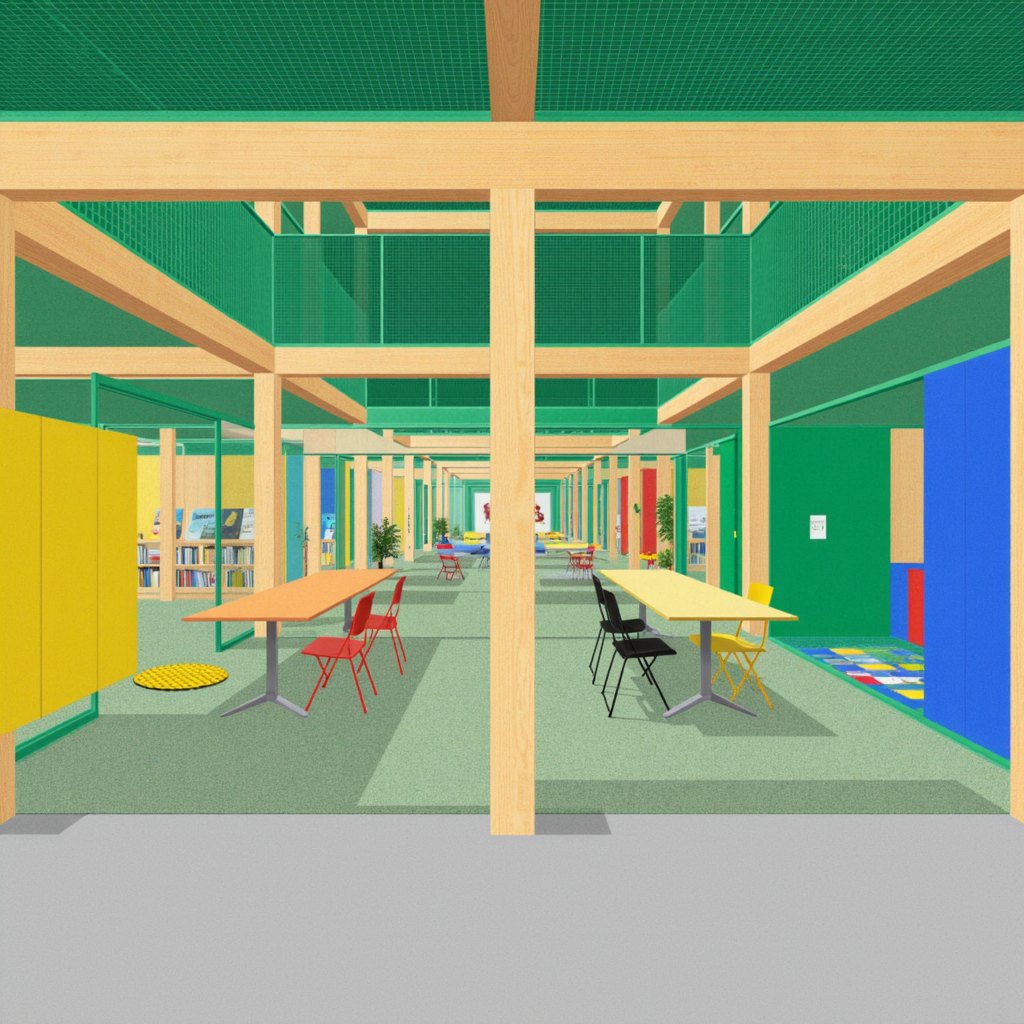
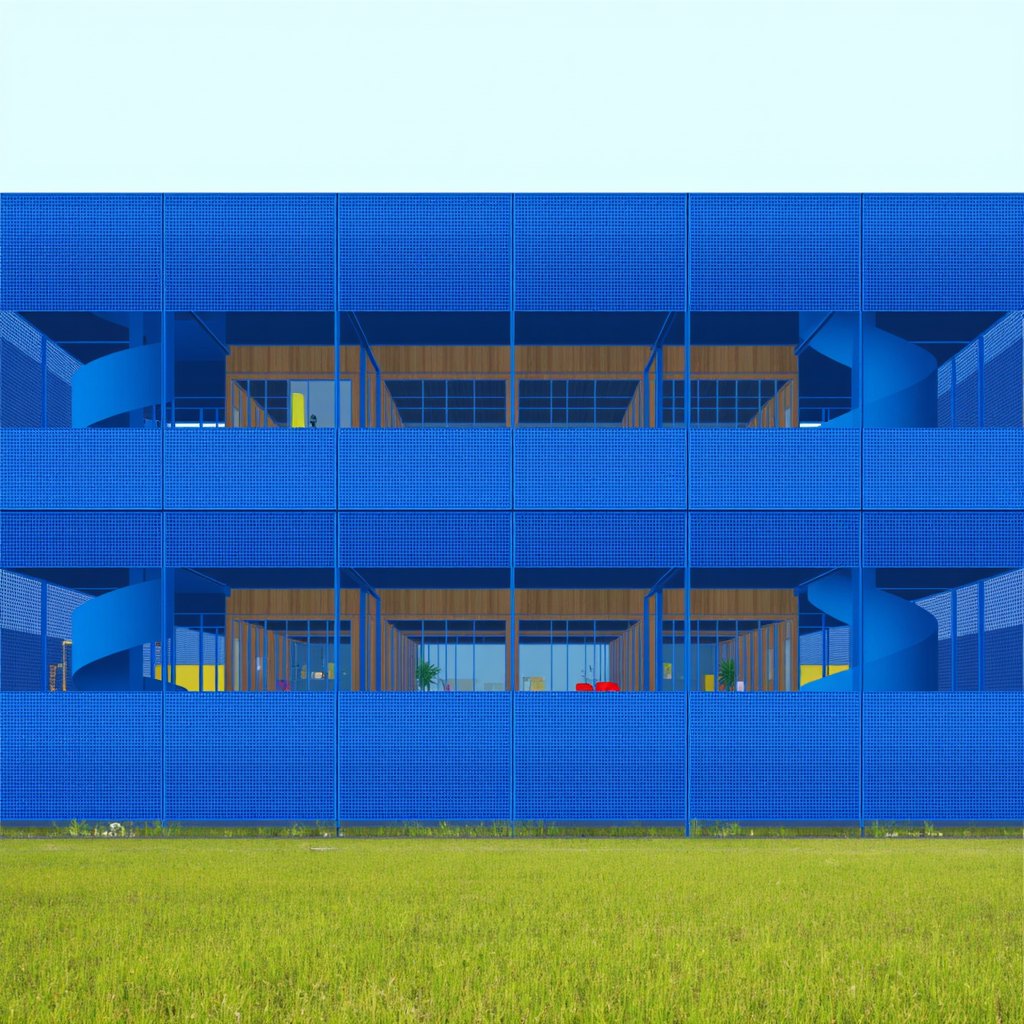
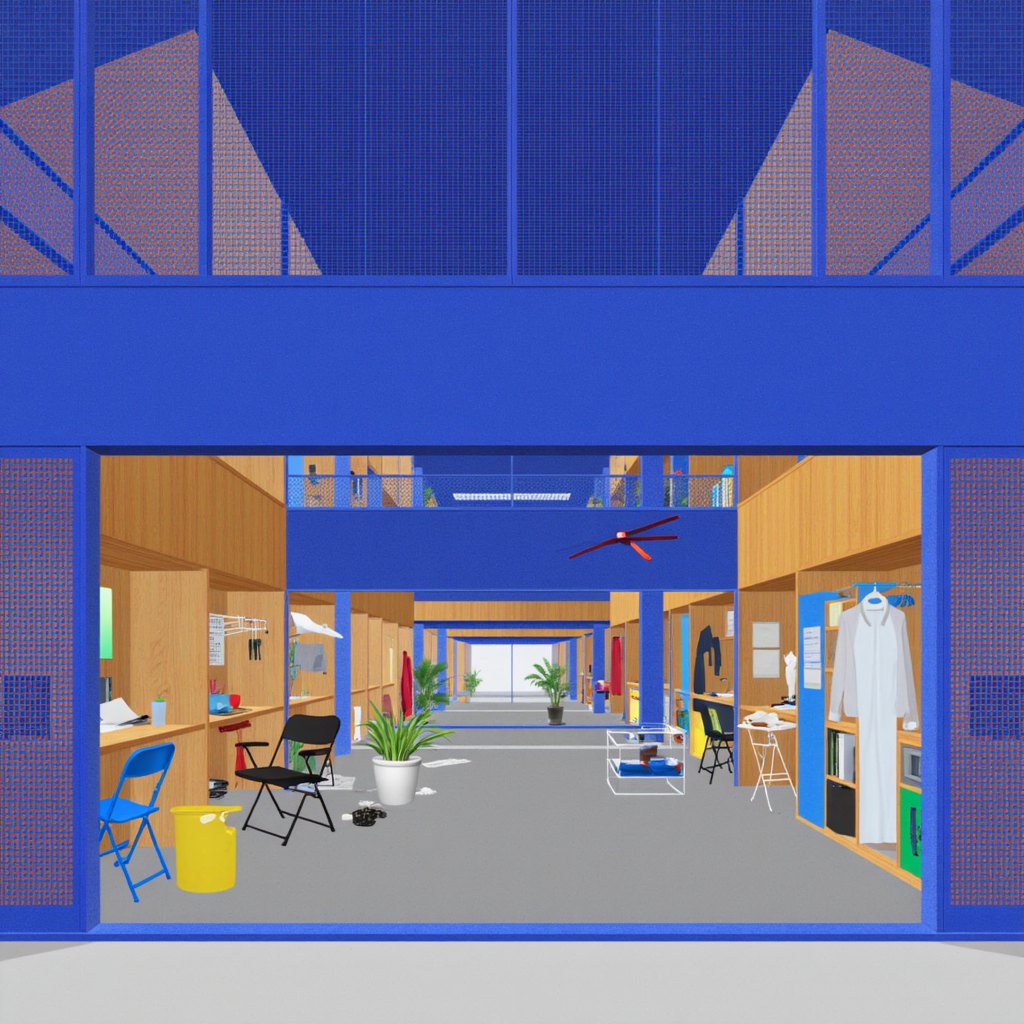
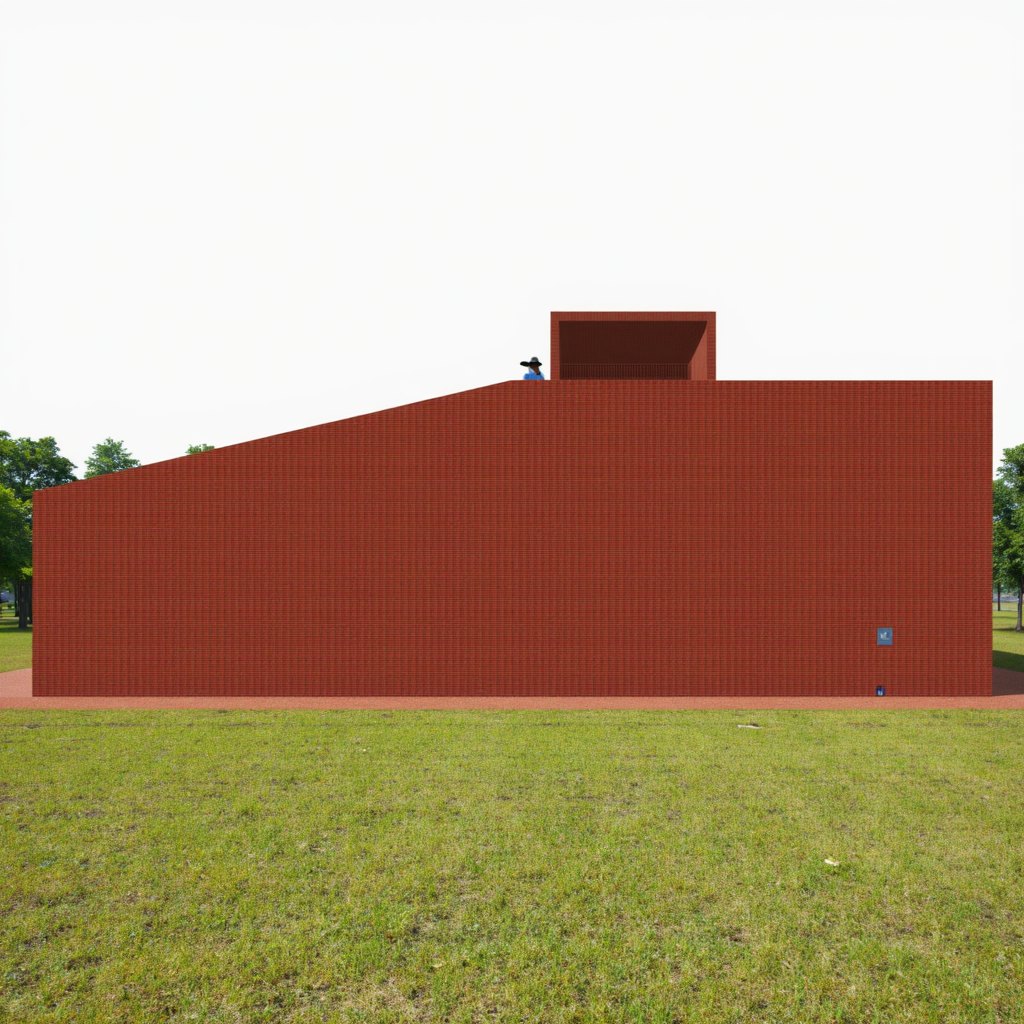
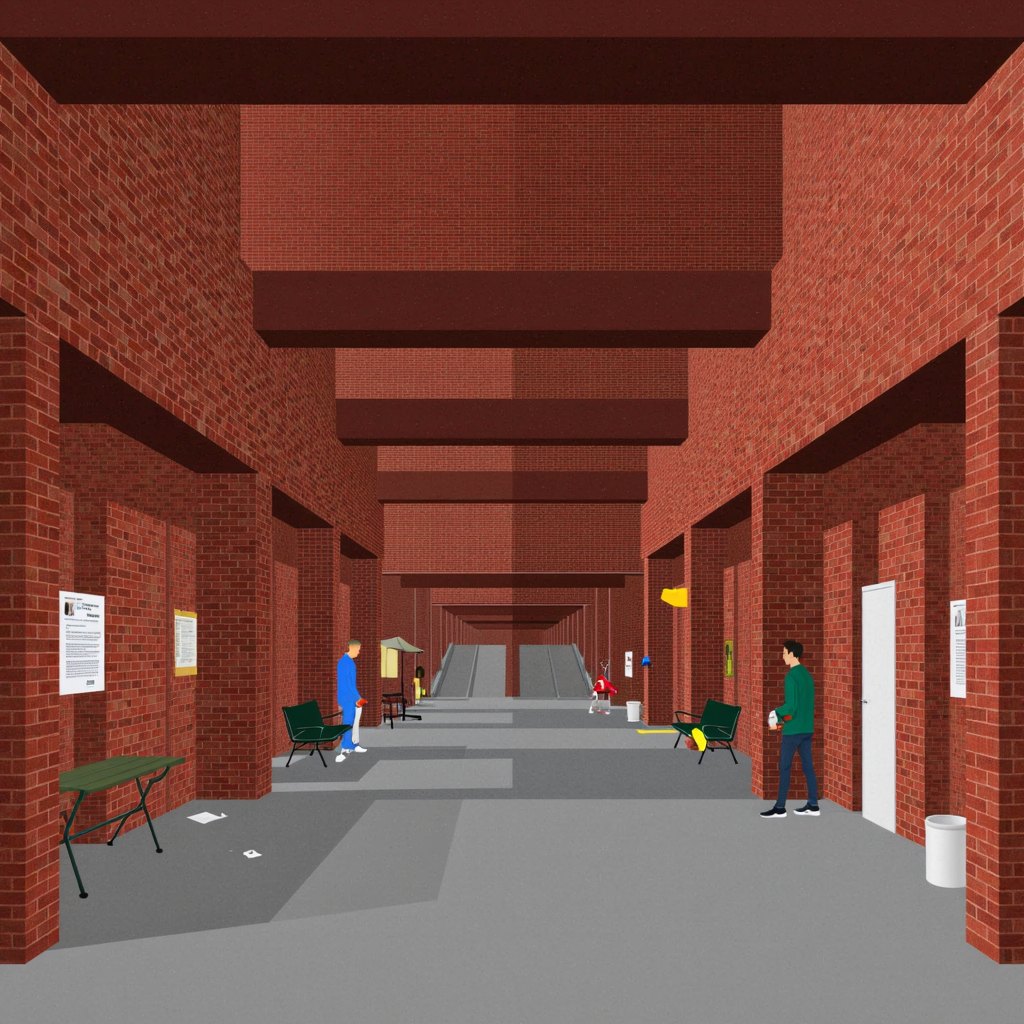
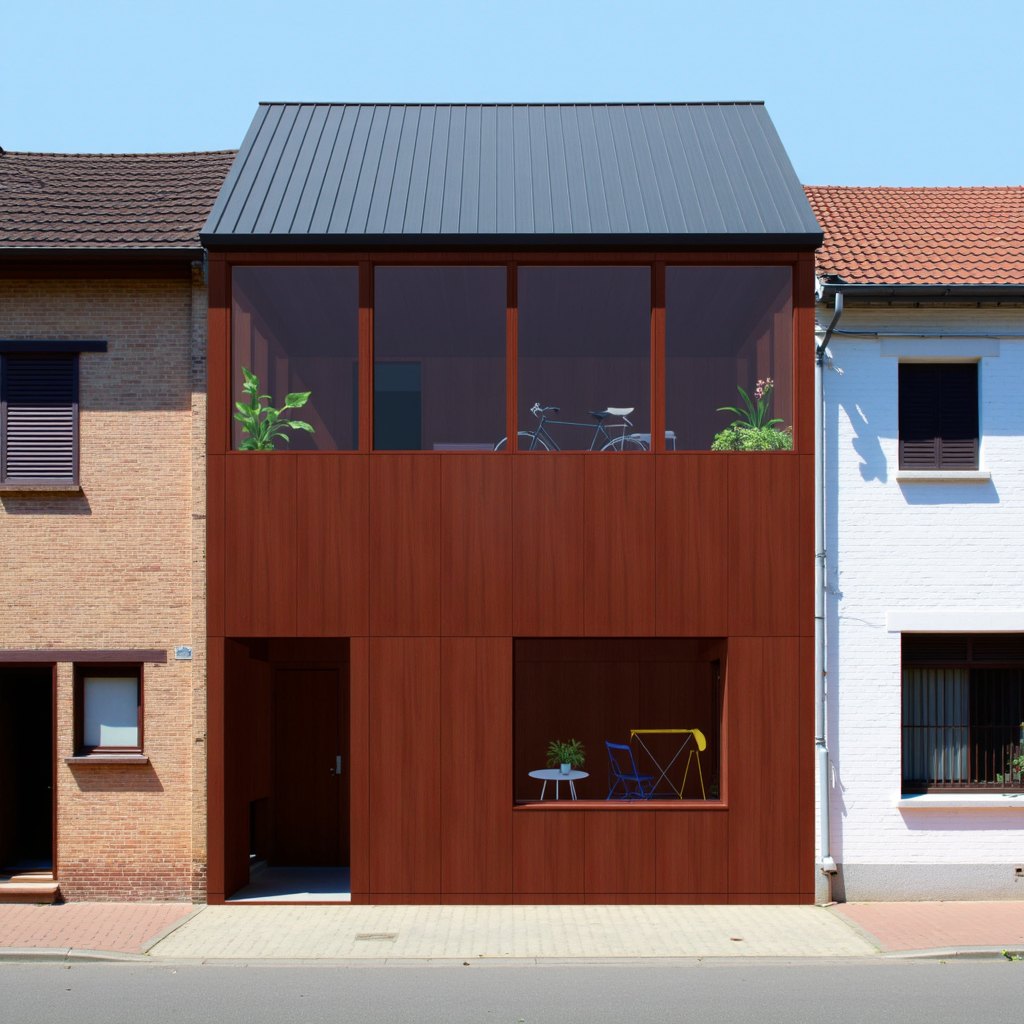
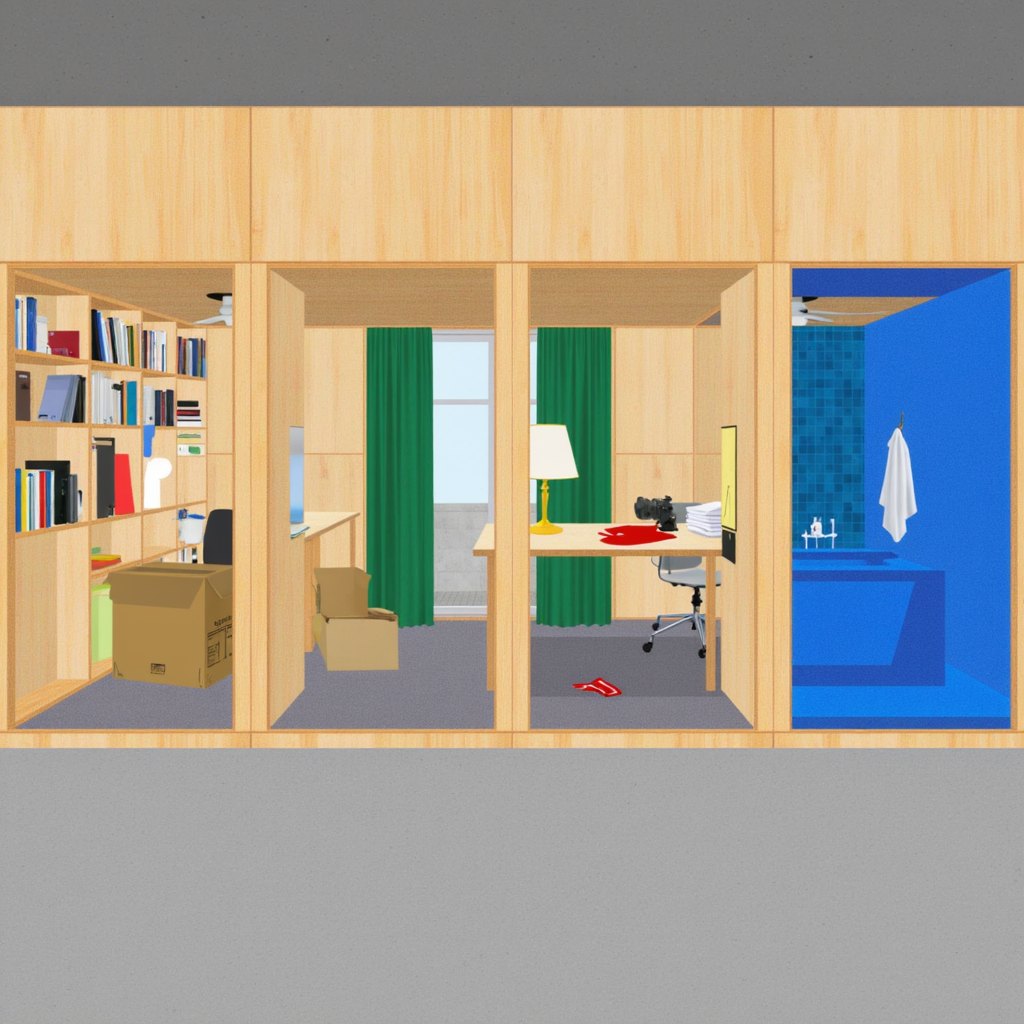
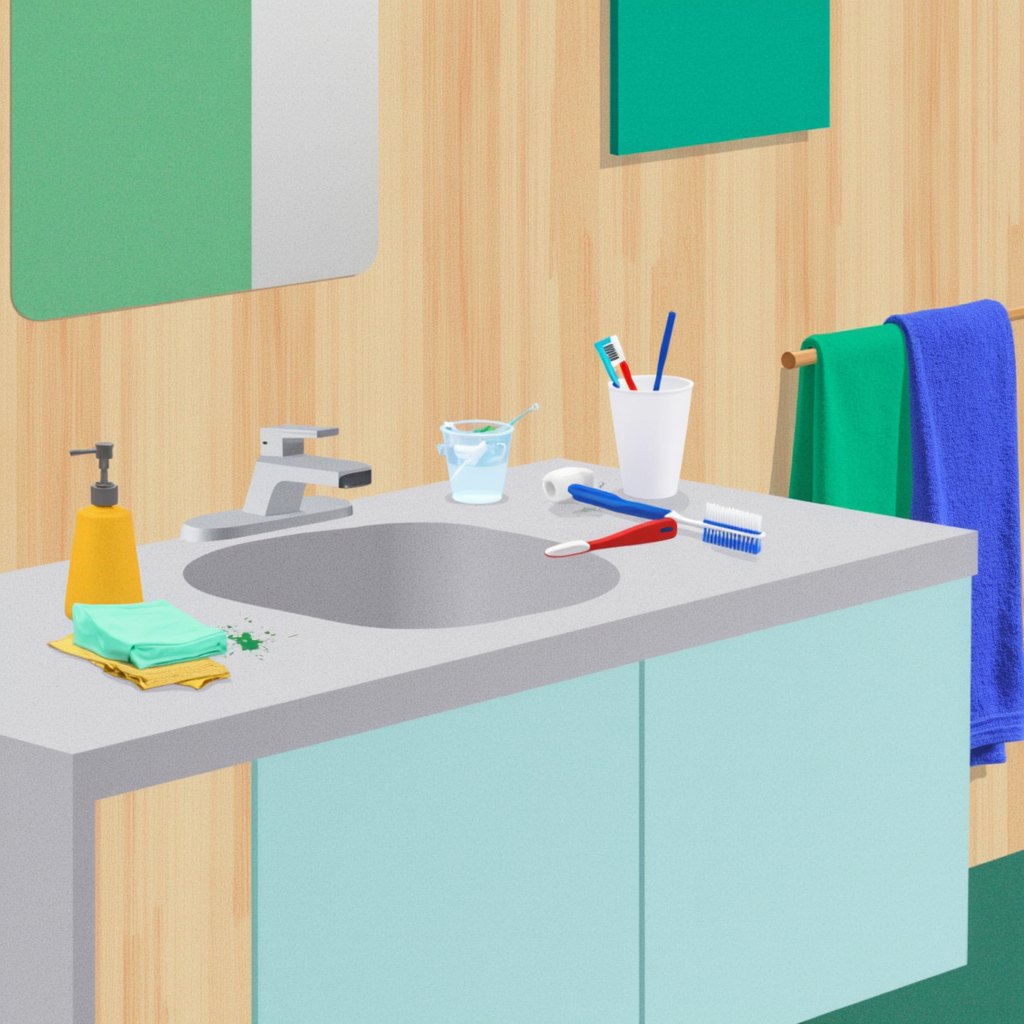
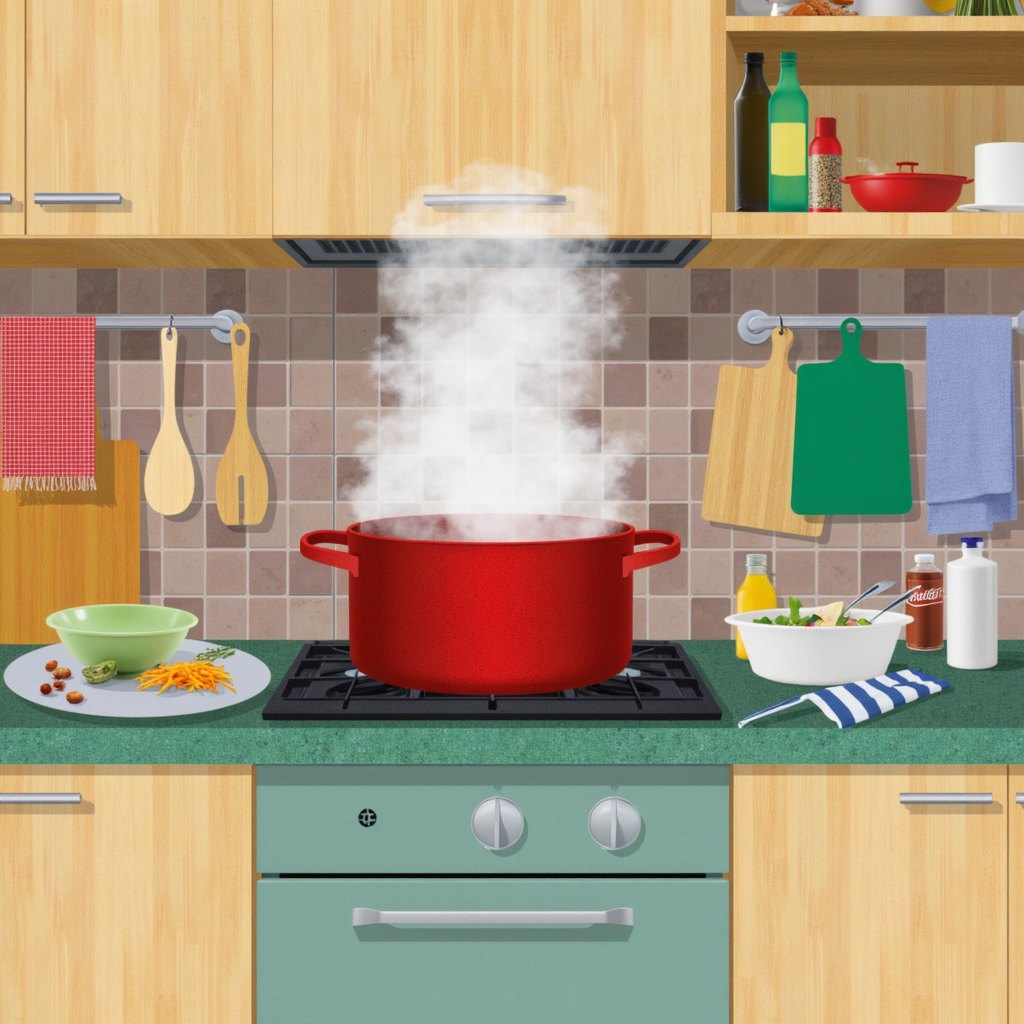
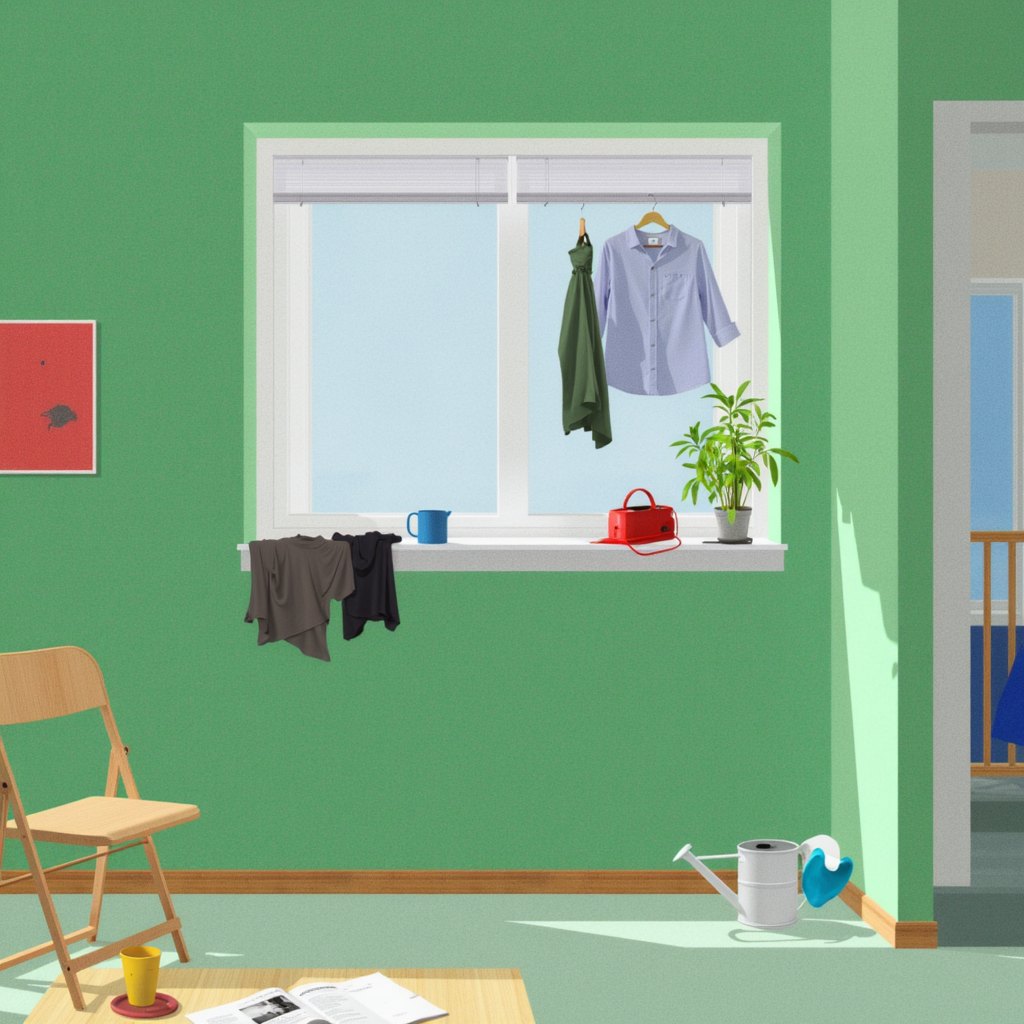
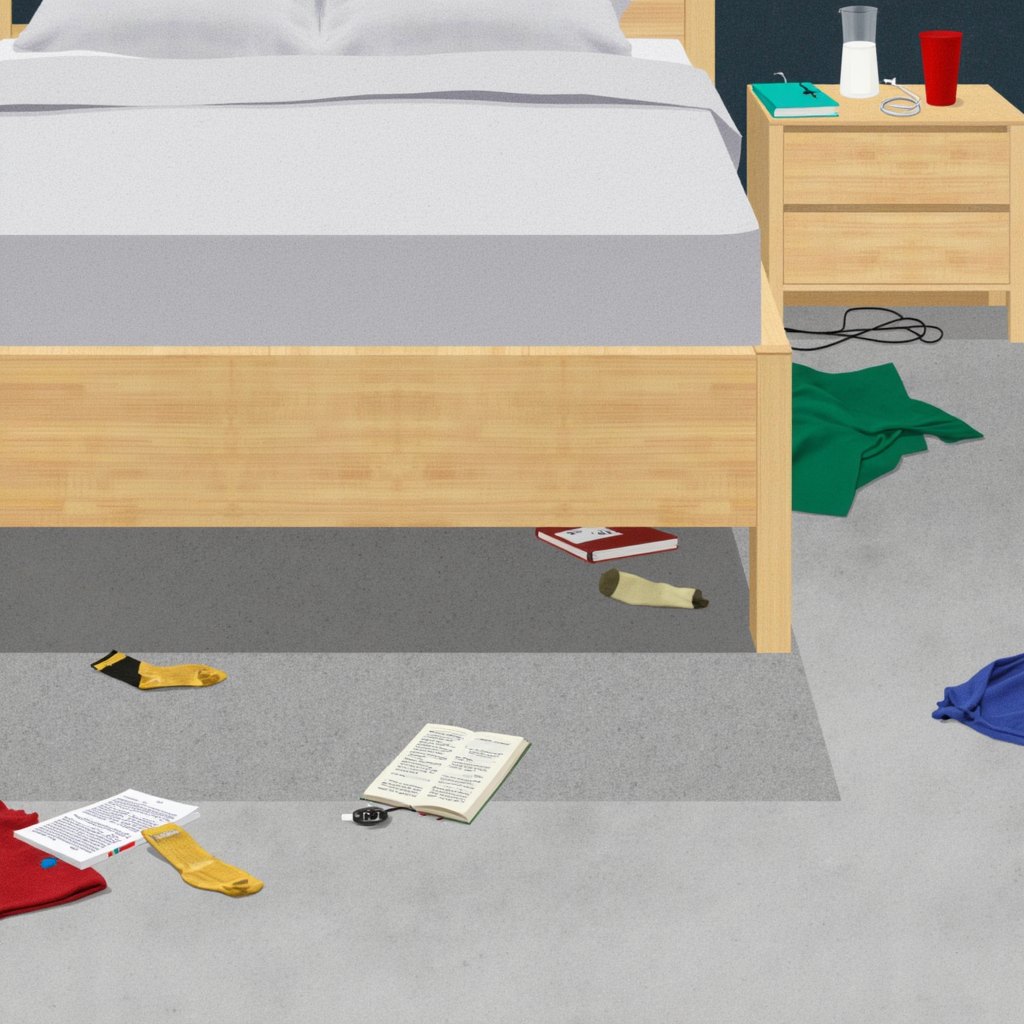
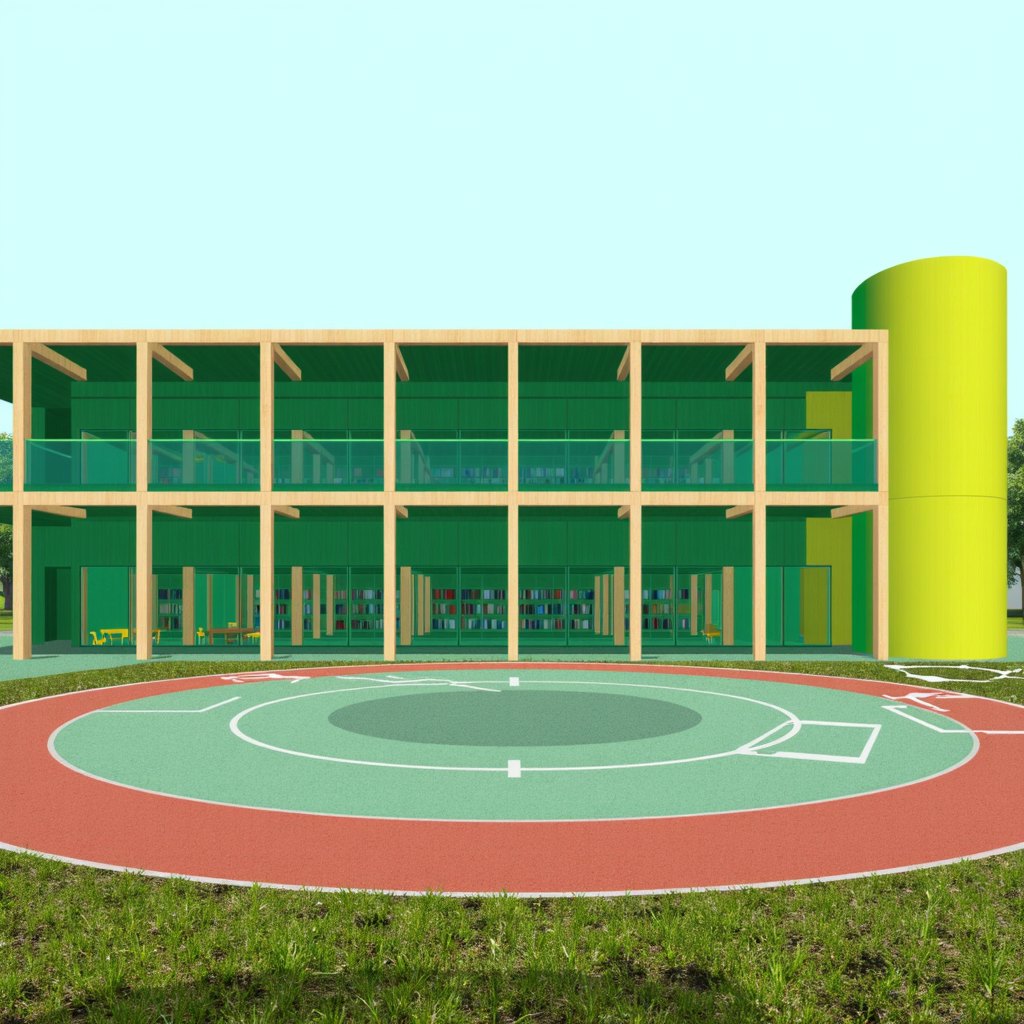
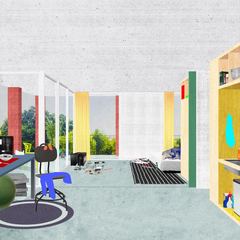
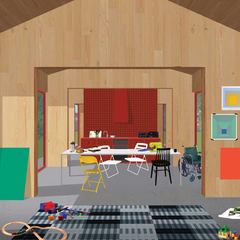
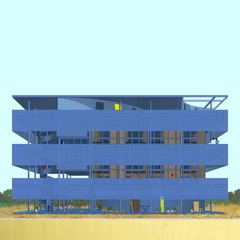
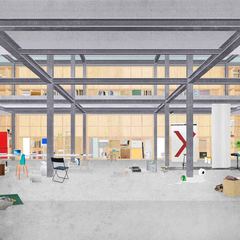
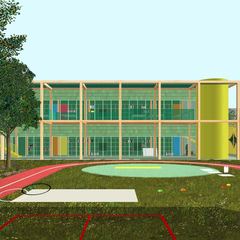
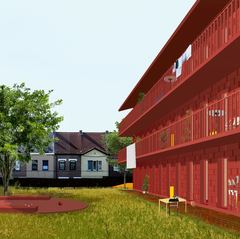
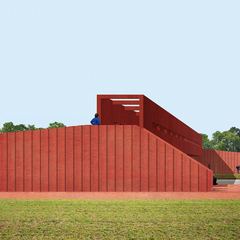
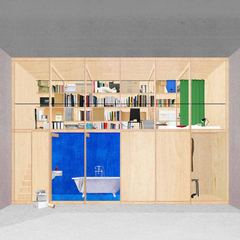
Dylan loves Dogma's collage style because it feels "real" and "unreal" at the same time, a three-dimensional world built from flat images (a 2.5D world). Earlier assignments showed that "realistic" AI images often look smudged and over-rendered, like a photo taken at too high an ISO. The hypothesis: a style built from lines, flat colour and simple shadows might avoid that.
What they did
- First tried image-to-image: feeding Dylan's own studio line drawings in to get a Dogma-style collage. It didn't work.
- Switched to text-to-image with a LoRA trained on Dogma-style images, each with a long, specific caption.
- Planned the series as "8 + 4". Four buildings each got an exterior and an interior view, then four close-ups of everyday details: a bathroom sink, a steaming pot, socks by a bed, laundry by a window.
What they found
- The hypothesis held. The images avoided the smudged texture and read clearly as a whole.
- Some details still broke real-world logic, but the overall effect went past Dylan's expectations.
- Very specific, everyday prompts worked too. The model seemed to really take on the style and build a consistent 2.5D world.